I’m trying to use the newest version of the matrix code to create some grammars and then compile them and parse test profiles with ACE and ART. However I’m getting this error with ACE:
reading trigger-rule        from `/overflow_projects/ecconrad/ecc-thesis/outputs/201125_1053/grammars/yaq/yaq1/ace/../trigger.mtr'
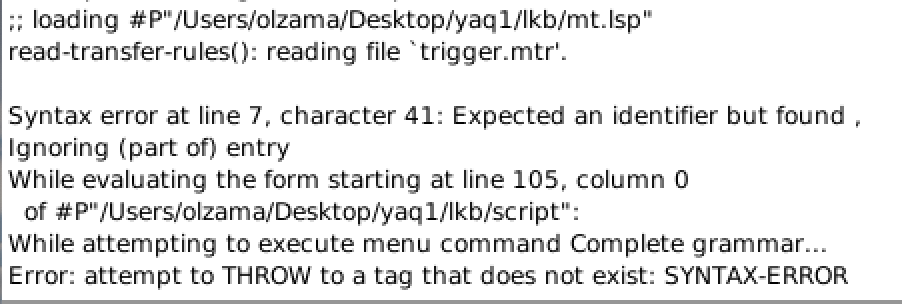
tdl: expected a dag definition
hint: structify -> rdagify failed
hint: structify -> rdagify failed
hint: listify failed
hint: structify -> rdagify failed
tdl: top-level error occured near /overflow_projects/ecconrad/ecc-thesis/outputs/201125_1053/grammars/yaq/yaq1/ace/../trigger.mtr:9
I then also get this error with ART (but my hope is this is just because ACE is failing to compile the grammar and fixing that will solve this also):
reading results for                0	out of sync; arbiter sent 'this does not appear to be a grammar image.' when expecting a SENT or SKIP header.
failed to read result for 0
I was not getting these errors when using an old version of the matrix code that was in python2, so I assume this is a bug with the matrix code, but based on this ACE error I’m not sure where to look in the matrix code to try to squash it.
As a quick work-around, since you aren’t using these grammars for generation, you can remove the contents of trigger.mtr (or maybe it’s called triggers.mtr).
Update: removing the multiple ASPECT values does help; there is no longer a failure associated with trigger.mrt. (Note that there are lots of errors associated with the lexicon file; those you also get with the old Matrix code. Do you know about them?)
The syntax following ASPECT is invalid. Somehow you are specifying three comma separated values for ASPECT. TDL (and MTR rule) syntax is [ ATTRIBUTE1 value1, ATTRIBUTE2 value2 ]. What was the expected result?
This looks to me like the choices file did multi-select for the ASPECT value for that particular element. This should result in an underspecified supertype (disjunction of the specific types), but the code for generating the trigger rule isn’t getting that right. Not sure why this bug is showing up right now, but I guess it’s because AGG inference is serving as a stress-test
Removing the trigger info got me further, but now I am hitting some of those lexicon errors I believe:
UnicodeEncodeError: 'latin-1' codec can't encode character '\u0301' in position 2: ordinal not in range(256)
/overflow_projects/ecconrad/ecc-thesis/outputs/201125_1827/grammars/abz/abz4/ace/../roots.tdl: No such file or directory
1835 types (471 glb), 9 lexemes, 119 rules, 90 orules, 37 instances, 63 strings, 155 features
loaded grammar in 0.45017s
WARNING: not enough room in 128 bytes to record grammar information
The UnicodeEncodeError feels like an issue in the python, but the “not enough room” seems like either an ACE problem or an issue with the space in my directory. If it’s ACE I’m not sure how to go about fixing that
I think the ACE error about recording grammar information can safely be ignored. It most likely means the pathname you used to indicate the grammar config location was longer than expected, or something similar.
I can’t speak to the Unicode error you are having.
I found the source of this UnicodeEncode Error, this is in the tdl.py file in matrix/gmcs:
tdl_file = sys.stdout
tdl_indent = 0

def TDLwrite(s):
    global tdl_indent
    global tdl_file
    tdl_file.write(s) # <-- this line is failing
    i = s.rfind('\n')
    if i != -1:
        tdl_indent = len(s) - (i + 1)
    else:
        tdl_indent += len(s)
The issue is that it’s trying to write a non Unicode character to tdl_file which was set above to sys.stdout … and the terminal on patas is not set to use unicode apparently. I’m confused though because why would the tdl file be stdout and not iso.tdl ?
Regardless, I’ve at least pinpointed it to here.
UPDATE: … found out I had commented out the lines in my .bash_profile that set the terminal to be Unicode … so I think it’s fixed.
To go back to the bug with the syntax of the RELS list; how urgent it is to fix? That could well be my responsibility (unlike the lexicon). Is this something you need to do many times (create these grammars)?
I do create the grammars every time I run my system, but the fix Emily provided of emptying out the trigger.mtr file allowed me to progress past that. So for now after the grammars are created, I just use a shell command to clear out that file since I don’t use them for what I’m doing. So it’s not blocking me personally.
Sorry for getting to this late! But that’s exactly what I have in mine I should be sure to add a note about this to my startup README though… thanks for reminding me about this issue!

 found out I had commented out the lines in my
 Would you mind letting me know what you specifically had in your .bash_profile that fixed it?